Qihua Dong's

I am currently a PhD at Northeastern University, Boston. I graduated from City University of Hong Kong with a major in computer science and a minor in math.
My research interests focus on reasoning and visual understanding in (M)LLMs, including reinforcement learning and tool-use agents. My prior experience spans multimodal LLMs, image segmentation, and medical image analysis.
ps: You may reach me by email or GitHub. Welcome to collaborate!
News
| Aug 2026 | Our Ref-Adv-s benchmark is now integrated into EvalScope (ModelScope), with support for standardized evaluation and report generation. Check out the evaluation guide! |
|---|---|
| May 2026 | Excited to join Meta SuperIntelligence Lab as a Research Scientist Intern, working on multimodal LLM training! |
| Apr 2026 | Two papers accepted at ACL 2026: a Findings paper on a hierarchical visual agent with compact visual/text context for chart reasoning, and a Main Conference survey on thinking with images. |
| Mar 2026 | Our Amazon work, Visual Reasoning through Tool-supervised Reinforcement Learning, was accepted to CVPR 2026 Findings and is now available on arXiv. If you find it interesting, feel free to upvote it on Hugging Face Papers. |
| Mar 2026 | The code and data for our ICLR 2026 paper Ref-Adv: Exploring MLLM Visual Reasoning in Referring Expression Tasks are released at ref-adv.github.io. |
Projects
The authors with * contributed equally to the work-
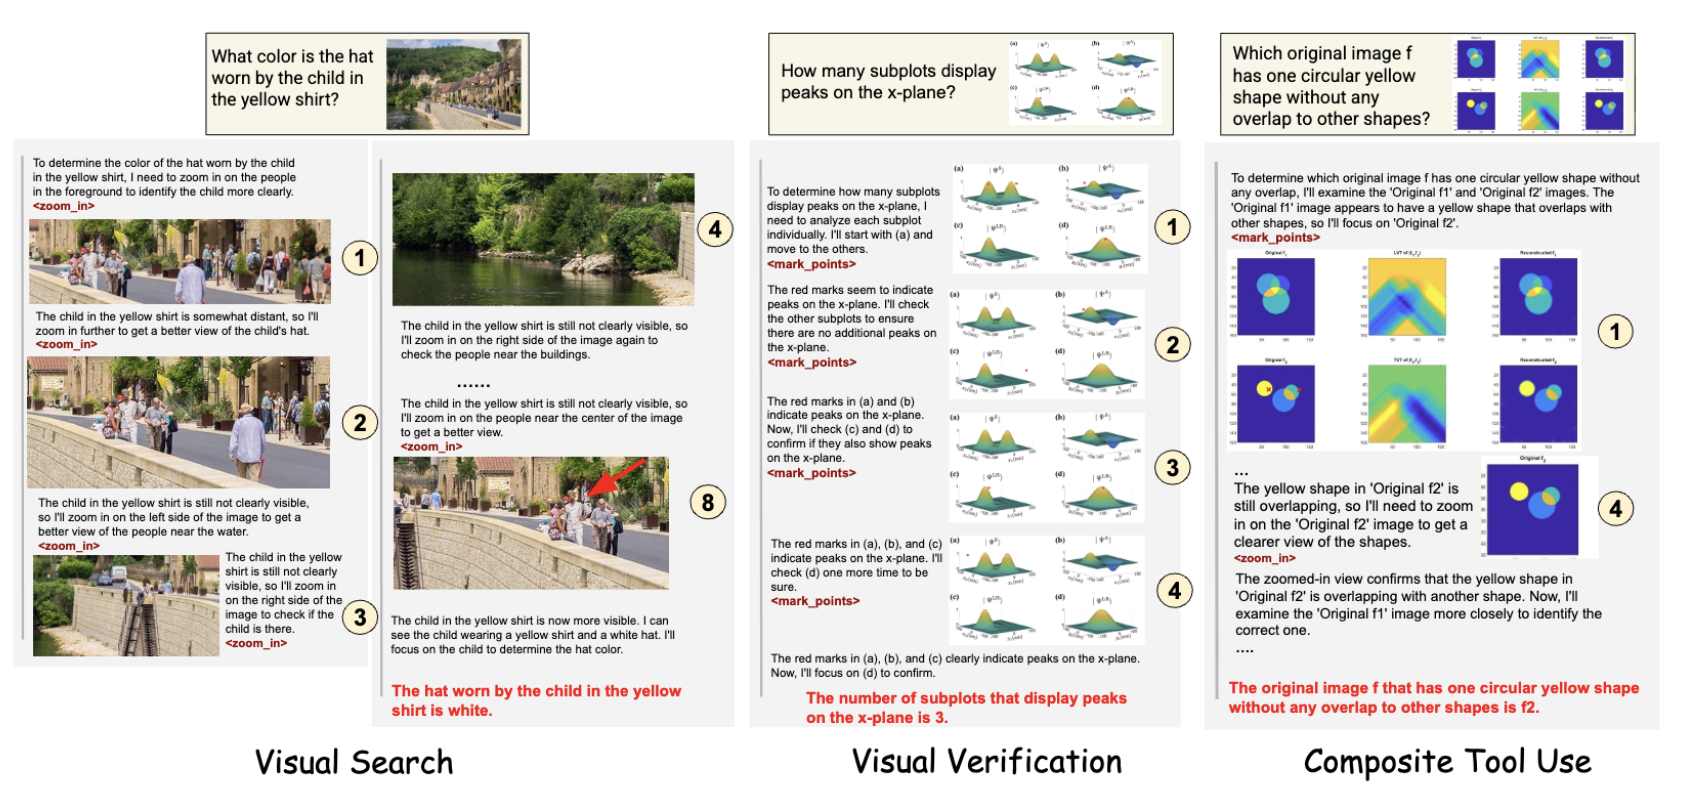 CVPR 2026 Findings, 2026
 Internship Work
-

-
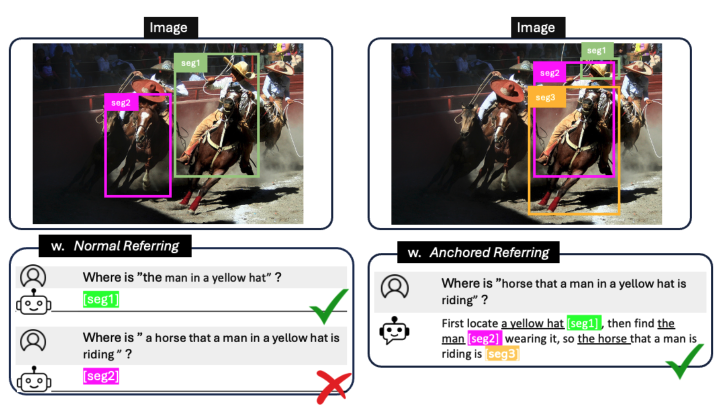 arXiv preprint, 2025
 Internship Work
-
-
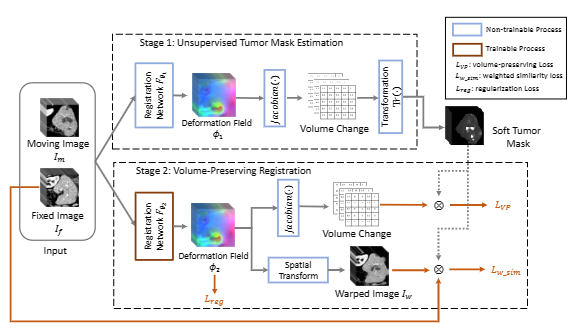
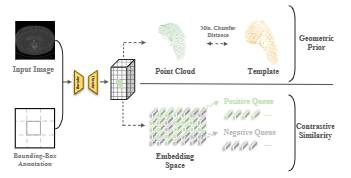 IEEE Transactions on Medical Imaging, 2023